Configuration
Open System > Embedding Configuration in Pimcore Studio. The screen is admin-only. It has four tabs — General, Scope, Models and Usages — and a toolbar with Save, Save & Re-embed and Save & Full Re-embed.
Changes are stored in the settings store and take effect without a deployment. A few infrastructure settings have no editor and are configured in YAML, see Deploy-time YAML.
The editor opens read-only, with a warning and no Save button, whenever the configuration cannot be
written: when the configuration comes from YAML outside debug mode — a hand-written
pimcore_backend_power_tools.embeddings node is the usual case — or when the write target is disabled. See
Where the configuration is stored.
General tab
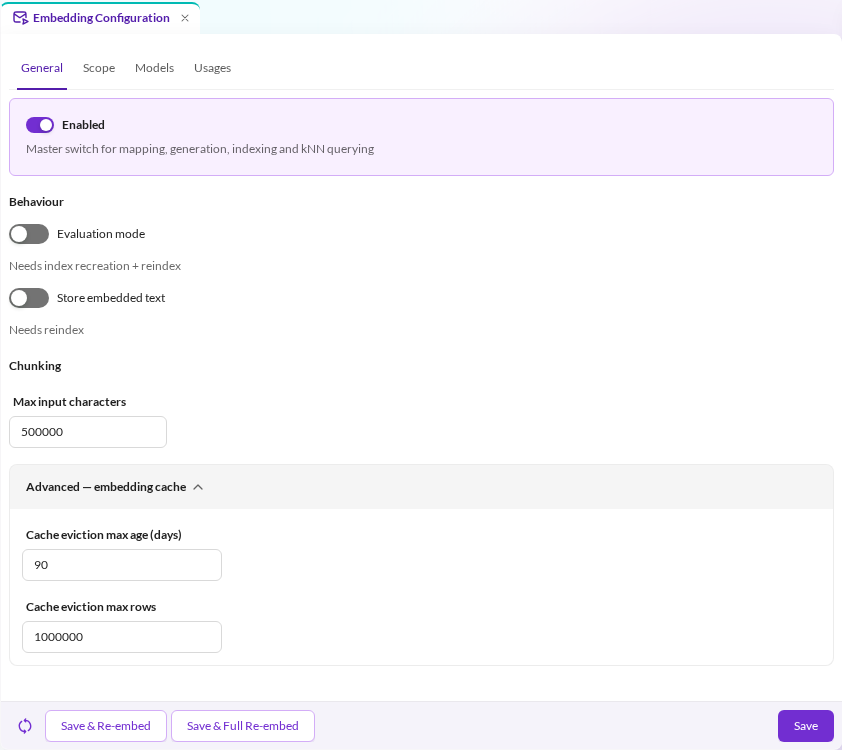

| Field | Default | Description |
|---|---|---|
| Enabled | off | Master switch for all embedding behaviour: mapping, generation, indexing and kNN querying. Off by default, because embeddings add index fields and send content to an external service. Switch it on and configure at least one model and one usage. |
| Evaluation mode | off | Maps, generates and stores every text representation per element so the Evaluation Tool can compare them. Off, only the primary representation is stored. Needs index recreation and a reindex. |
| Store embedded text | off | Debug aid: also stores the composed element text in an emb_<model>_source sibling field, without the model's document prefix. Text inputs only; image inputs are never stored. Costs storage — keep it off in production. |
| Max input characters | 500000 (min 2000) | Cost guard: composed text beyond this is truncated before chunking, which bounds how many embedding requests one element can cause. About 590 chunks at the default. |
| Cache eviction max age (days) | 90 (min 1) | Under Advanced — embedding cache. Cache rows untouched for longer than this are pruned by bpt:embeddings:reindex --evict. |
| Cache eviction max rows | 1000000 (min 1) | If the cache table is still over this row count after age-based pruning, the least recently used rows are removed down to the cap. |
Max input characters changes cost, not quality: nested kNN ranks by the best-matching chunk, and a long
document occupies one result slot however many chunks it has. Lower it on installations with many long
documents; above the default, prefer splitting the source document. The hard ceilings are the search
engine's — OpenSearch allows 10,000 nested objects per document, and one bulk request must stay under
http.max_content_length.
Scope tab
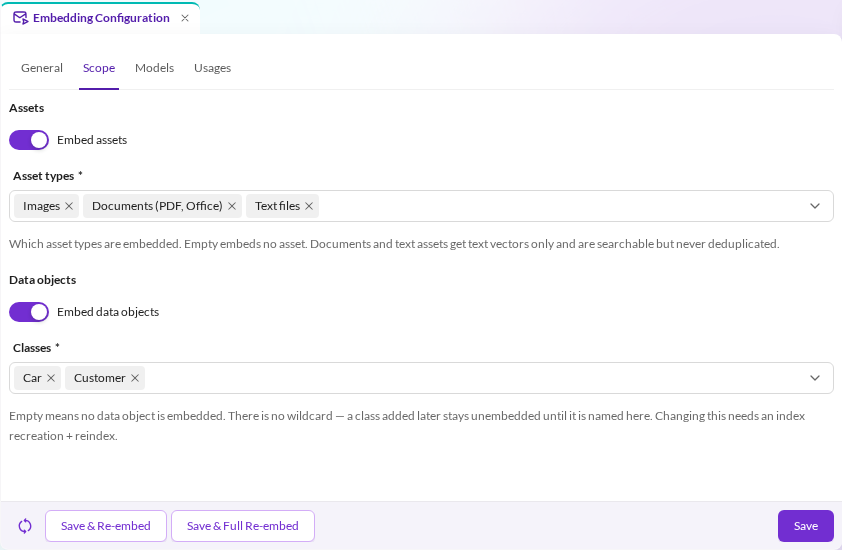
Which elements are embedded. Both sides deny by default: enabling embeddings alone embeds nothing, because sending a catalogue to an inference service should be a decision, not a side effect.

| Field | Default | Description |
|---|---|---|
| Embed assets / Asset types | off | Images, Documents (PDF, Office) and Text files. Switching Embed assets off is the same as selecting no type. Documents and text files produce text vectors only. |
| Embed data objects / Classes | off | The data object classes to embed. There is no wildcard: a class added later stays unembedded until it is named here. |
Document and text assets are searchable once embedded, but they never enter duplicate detection — asset dedup
requires Images.
Widening the scope needs the affected index's mapping updated before it can carry vectors. Save & Re-embed does this for you. Until the mapping exists, newly scoped elements index without their vector fields and are marked for backfill, so their vectors are filled in on that run — no manual reindex needed.
What is extracted from an asset
Document and text assets are embedded from their identifying context (name, path, metadata) plus whatever text can be extracted. Max input characters governs how much: the extractors stop reading once they have delivered that many characters, because the chunker would discard anything beyond it.
| Source | Extraction route | Limit |
|---|---|---|
| PDF, Word, PowerPoint and other office documents | Pimcore core text extraction (pdftotext/Ghostscript for PDF, Gotenberg or LibreOffice for office formats); needs pimcore.assets.document.process_text | cut at Max input characters |
Spreadsheets and CSV (.xlsx, .xlsm, .ods, .xls, .csv) | PhpSpreadsheet, data only, row by row with the header once per sheet | rows are emitted until the text reaches the cap; a notice names the asset, sheet and row it stopped at. A workbook over 32 MB uncompressed is skipped; at most 256 columns per row and 200,000 cells per workbook are loaded |
Plain text (.txt, .md, .json, .xml, …) | file read | the first 4 bytes per character of the cap (2 MB at the default), cut at a UTF-8 character boundary |
| Scanned or image-only PDFs | no OCR anywhere in the chain | only name, path and metadata are embedded |
Extraction never fails to index: an unreadable or malformed file logs one warning, and the asset is embedded from its identifying context alone. The reasoning behind the fixed memory guards is in Defaults and Benchmarks.
Models tab
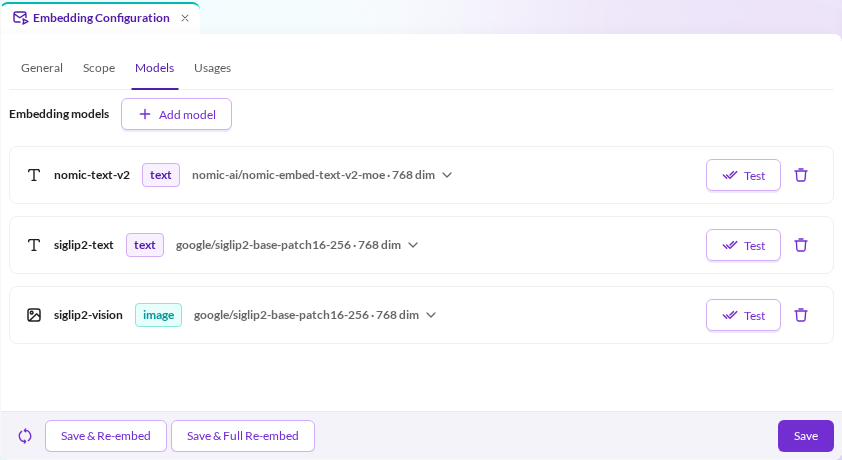
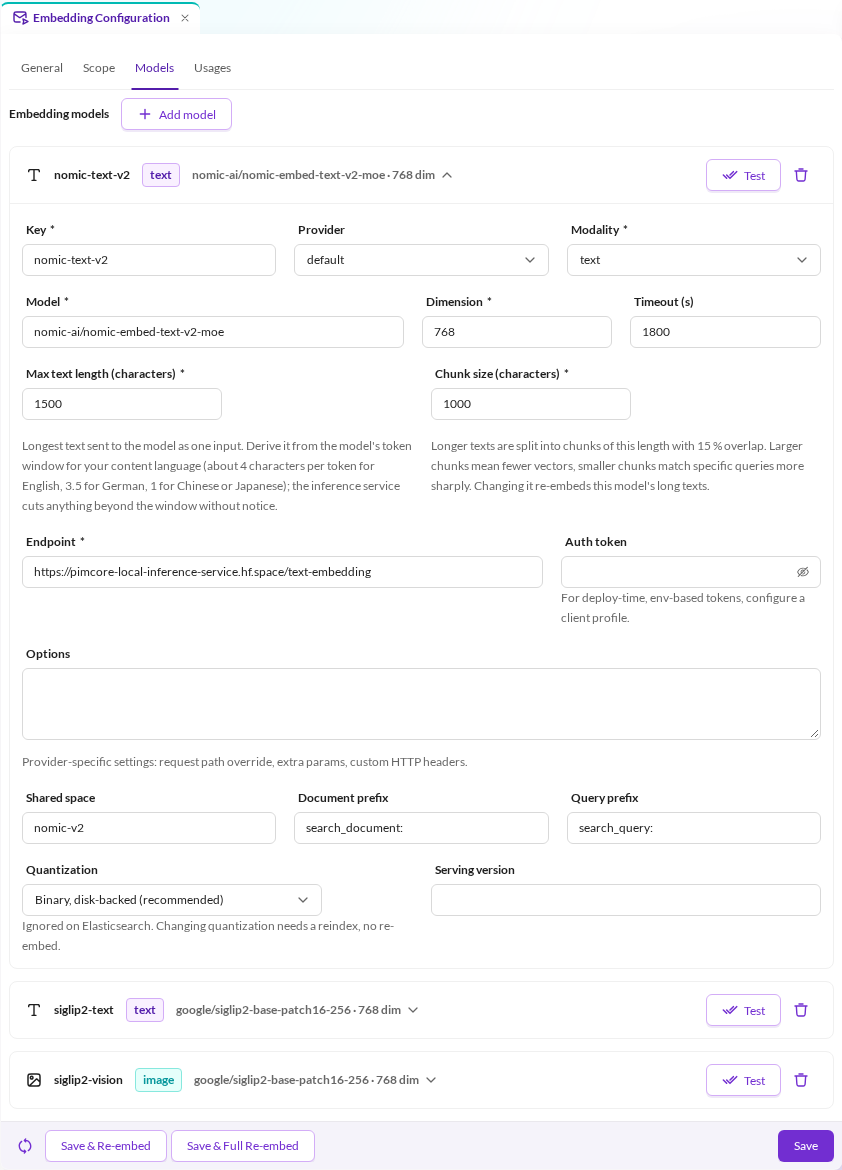
One card per embedding model. Add creates a card, the bin icon deletes one, and Test probes the endpoint.


| Field | Default | Description |
|---|---|---|
| Key | (required) | A free id you choose, referenced on the Usages tab. Dashes are folded to underscores internally: a model keyed nomic-text-v2 is addressed as nomic_text_v2 by CLI flags like --model=<id>. |
| Provider | default | Which registered provider talks to the endpoint, see Custom Embedding Provider. |
| Modality | (required) | text or image. |
| Model | (required) | The model name the inference service should load. Not part of the identity key: swapping it under the same key does not invalidate stored vectors — bump Serving version alongside it. |
| Dimension | (required) | The vector dimension the model returns. It sizes the kNN field mapping, which is immutable once the index exists, and every provider response is validated against it, so a misconfigured endpoint is rejected instead of poisoning the index. |
| Max text length (characters) | 1500 (min 200) | The longest text sent to the model as one input; longer text is split into chunks. See Sizing the character budgets. Text beyond the model's real window is truncated by the inference service without notice. Ignored for image models. |
| Chunk size (characters) | 1000 (min 100, ≤ max text length) | Chunk length for longer text; the overlap is 15 % of it. Larger values cut the vector count of long documents roughly in proportion; smaller values match specific queries more sharply. Changing it changes the chunk texts, so that model's long texts re-embed. |
| Endpoint | (required) | Base URL of the HTTP inference service. Must be an absolute http:// or https:// URL. |
| Timeout (s) | 120 | Request timeout. Embedding batches on CPU-only services can be slow. |
| Auth token | empty | Optional bearer token. Literal values only — %env(...)% is rejected. For an env-backed secret use a client profile. |
| Options | empty | A JSON object of provider-specific settings, passed through untouched. The default provider reads params (extra request body params) and headers (custom HTTP headers). |
| Thumbnail | (required for image models) | The Pimcore image thumbnail used as the model input, see The image thumbnail. |
| Shared space | empty | Name of the latent space the model embeds into. Two models may only be combined in one search (a text query against an image field) when both declare the same space. Equal dimensions are not sufficient and would return confident nonsense. |
| Document prefix / Query prefix | empty | Instruction prefixes some models expect, for example search_document: / search_query: for Nomic, passage: / query: for E5. The bundle prepends them, so the endpoint must not add its own. Only Document prefix is part of the identity key: editing it re-embeds that model's text vectors, while Query prefix only re-keys the query cache. |
| Quantization | Binary, disk-backed | See Quantization. |
| Serving version | empty | A version marker for the inference service's preprocessing, folded into the identity key. Bump it when serving-side preparation changes (a tokenizer fix, a normalization change, a new API-version header). Such changes are invisible to the text-based key, so stored vectors would otherwise stay silently stale. |
Endpoint, Model, Provider, Dimension, Timeout, Options and the custom headers are transport or lookup details and are not part of the identity key. If one of them changes what the service actually computes, bump Serving version alongside it, see When vectors are regenerated.
Testing a model
Test sends one probe request to the endpoint with a short, fixed 15-second timeout, using the values currently in the form — including unsaved ones. On success it reports the round-trip time and the dimension the endpoint actually returned; on failure it reports the error. Use it before saving a new model.
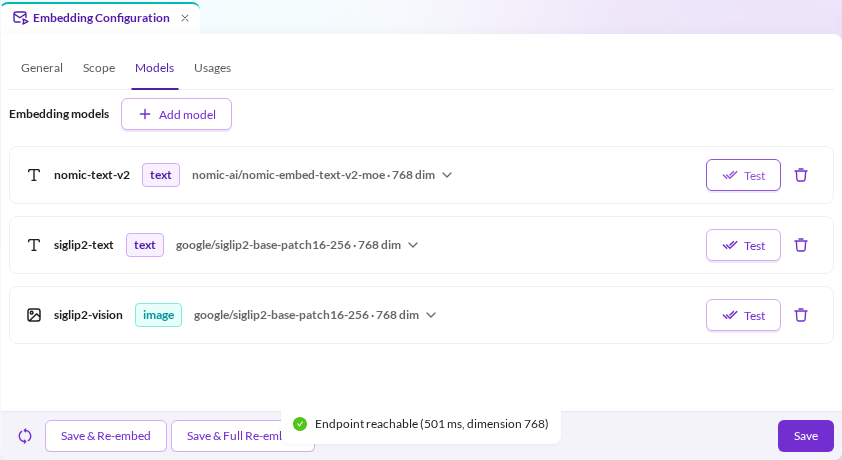

When the form's Auth token is left empty, the test falls back to the token already stored for that model's key, rather than testing with no auth at all.
Quantization
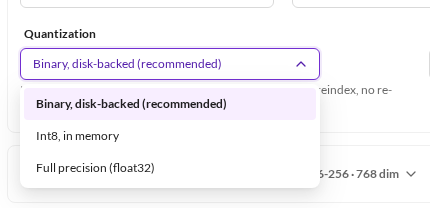

The select offers the three combinations measured against the quality bars in Defaults and Benchmarks:
| Preset | OpenSearch mode | Compression |
|---|---|---|
| Binary, disk-backed (recommended) | on_disk | 32x |
| Int8, in memory | in_memory | 4x |
| Full precision (float32) | in_memory | 1x |
A stored pair that matches none of the three — from YAML, or from an older configuration — is shown as a fourth, read-back Custom entry naming the actual mode and level.
Quantization is ignored on Elasticsearch. Changing it needs a reindex but no re-embed: the vectors carry over via index recreation.
Sizing the character budgets
Both budgets are in characters, because the bundle has no tokenizer: provider, endpoint and model are all replaceable and none exposes one. Convert the model's token window yourself:
usable_tokens  = window_tokens − tokens(document prefix) − 10 % of window_tokens
max_text_chars = usable_tokens × chars_per_token(language)
chunk_chars    = 250 × chars_per_token(language)          # ~250 tokens is the retrieval convention
window_tokens is on the model card (nomic-embed-text-v2-moe 512, nomic-embed-text-v1.5 8192,
Qwen3-Embedding 32k). The 10 % margin covers the spread of real texts around the language average. For the
default model and the Nomic prefix: 512 − 6 − 51 ≈ 455 usable tokens.
| Content language | Chars per token (approx.) | Max text length | Chunk size |
|---|---|---|---|
| English | 4 | 1800 | 1000 |
| German, French, Spanish, Italian | 3.5 | 1500 | 875 |
| Russian, Greek | 3 | 1350 | 750 |
| Arabic, Hebrew, Hindi | 2 | 900 | 500 |
| Chinese, Japanese, Korean, Thai | 1 | 450 | 250 |
One model has one budget. For mixed-language content, size for the densest language you index; the other languages then produce more, smaller chunks, which costs vectors but loses no text. See Chunking.
The image thumbnail
An image model embeds a Pimcore image thumbnail of the asset, never the original file. Define a thumbnail matching the dimensions your model expects:
pimcore:
    assets:
        image:
            thumbnails:
                definitions:
                    embeddings_siglip2:
                        name: embeddings_siglip2
                        description: 'Image input for embedding generation (SigLIP 2 base, 256x256)'
                        format: JPEG
                        quality: 90
                        items:
                            - method: cover
                              arguments:
                                  width: 256
                                  height: 256
- Match the model's native input.
siglip2-base-patch16-256takes 256×256; feeding it 224 makes the service upscale and lose detail. A larger thumbnail is downscaled correctly, so err upward. - One per model. Two image models can use two definitions, for example 256 and 384.
- Editing it re-embeds. The definition's pixel-affecting settings are part of the identity key, so a resize invalidates exactly that model's images.
Custom request headers
Endpoints that do not authenticate with a bearer token, or need extra routing or tenant headers, are served
through the Options field instead of a custom provider. Configured headers are added to every request and
replace a same-named default, compared case-insensitively, so an Authorization entry wins over the
Auth token bearer default:
{
  "headers": {
    "api-key": "temporary-value"
  }
}
Like Auth token, header values are literal only: %env(...)% is rejected. Never put a real secret
here either — use a client profile. Headers are transport details
and are not part of the identity key; if a header changes what the service computes, bump Serving
version.
Usages tab
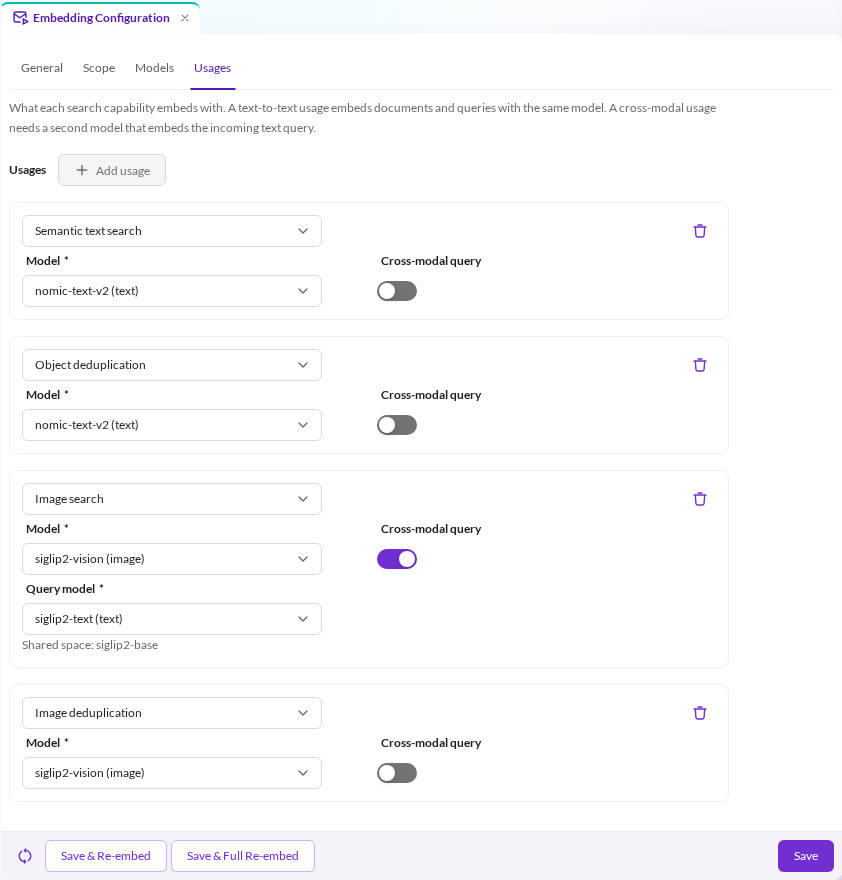
What each search capability embeds with. The four registered usages are Semantic text search, Object deduplication, Image search and Image deduplication. To add one of your own, see Registering a Custom Embedding Usage.

| Field | Description |
|---|---|
| Model | The model that embeds the indexed content, and — for a text-to-text usage — the incoming query too. |
| Cross-modal query | Switch on when the query is embedded by a different model than the content, which is what image search needs: a vision model indexes the images, a text model embeds the typed query. |
| Query model | Only with Cross-modal query. Both models must declare the same Shared space; the card shows which one is in effect. |
Deploy-time YAML
Three nodes live outside the editable configuration: they are infrastructure decisions, never persisted to the settings store and never editable through Studio.
Where the configuration is stored
The embeddings configuration is a Pimcore location-aware configuration: the read source and the write target are chosen per installation.
pimcore_backend_power_tools:
    config_location:
        embeddings:
            write_target:
                type: settings-store          # default; also: symfony-config, disabled
            read_target:
                type: ~                       # default; also: settings-store, symfony-config
| Setup | Behaviour |
|---|---|
| Defaults, as shipped | Reads container config first, settings store as fallback. A hand-written pimcore_backend_power_tools.embeddings YAML node therefore takes over and the editor turns read-only. Saves go to the settings store. |
write_target.type: symfony-config | Saves write YAML files into var/config/backend_power_tools_embeddings/, which are loaded back into the container configuration — a version-controllable workflow. Writing is only permitted in debug mode, so production editors are read-only under this target. |
write_target.type: disabled | The editor is read-only everywhere; the configuration is fully deploy-managed. |
Under a YAML override every field above is available as a configuration key. excluded_fields — field keys
that are never embedded, at any nesting level, by both production indexing and the evaluation tool — has
no editor and is only reachable this way, or through the API:
pimcore_backend_power_tools:
    embeddings:
        excluded_fields:
            - internalNotes
Changing it needs a reindex.
Credentials (embedding_client_profiles)
Auth token and the headers in Options are runtime-editable by anyone who can reach the configuration
screen, so stored values are literal-only: a %env(...)% placeholder in either is rejected at validation,
whether it comes from Studio or from YAML.
%env(...)% in embeddings.models.*.auth_token or .options.headers is always rejected. This is a
deliberate security control against env-var exfiltration through the editable configuration.
Env-backed secrets belong in embedding_client_profiles, a deploy-time-only node in config/packages/*.yaml.
Each profile attaches its token and headers to a request only when the request URL matches its
endpoint_pattern — an anchored regex, the same semantics as Symfony's ScopingHttpClient:
pimcore_backend_power_tools:
    embedding_client_profiles:
        my_inference_host:
            endpoint_pattern: 'https://inference\.example\.com/.*'   # anchored regex, escape literal dots
            auth_token: '%env(MY_INFERENCE_TOKEN)%'                  # container-resolved — safe here
            headers:
                X-Tenant: 'catalog'
Rules, in order of precedence:
- A stored literal token always wins. If the model's own Auth token is set, the matching profile's token is never used. Profiles are a fallback, not an override.
- Profile headers only fill gaps. A profile header is added only when the model does not already define a header of the same name, compared case-insensitively.
- No match, no credentials. If no
endpoint_patternmatches the request URL, nothing is attached. - Non-absolute endpoints never receive profile credentials.
Stored tokens are write-only through the API
The editor's underlying API never returns a stored token. A GET exposes only hasAuthToken: boolean; a
save distinguishes three cases for the authToken field:
| Sent value | Effect |
|---|---|
omitted / null | Keep the stored token for that model key unchanged. |
"" | Clear the stored token. |
| any other value | Overwrite the stored token. |
In the editor this is the Clear stored token checkbox next to a token field whose placeholder reports
that one is stored. Renaming a model key does not inherit its old token: the keep-on-null behaviour is
looked up by key, so a model saved under a new key starts with an empty token. Re-enter it after a rename.
Cache table (embedding_cache)
Where the durable vector cache table lives and which engine it uses:
pimcore_backend_power_tools:
    embedding_cache:
        database: ''              # optional schema for the cache table; empty = Pimcore's main schema
        table_storage_engine: ''  # explicit engine; empty = auto-detect at table creation
| Option | Default | Description |
|---|---|---|
database | '' | Optional schema name on the same MySQL/MariaDB server. Empty keeps the table in Pimcore's main schema. Must match ^[A-Za-z0-9_]*$. Cross-schema DDL is not something the installer or a Doctrine migration on this connection can express, so both skip creating the table and print the manual CREATE TABLE statement instead, see Provisioning the table. |
table_storage_engine | '' | Storage engine for the cache table. Empty auto-detects one at table-creation time, see Storage engine. An explicit value is verified to exist on the server and bypasses auto-detection. Only takes effect at table-creation time; neither the installer nor the migrations ever ALTER an existing table onto a different engine. |
Vector storage, reuse and index recreation
Vectors live in the search index documents and in a durable MySQL/MariaDB cache table, and are reused via version-aware identity keys, so re-indexing unchanged content costs no inference calls. The cache table, the identity key and the ways to force a re-embed are covered in Caching.
How the defaults were chosen
The measured reasoning behind the default model, text representation, chunking and compression choices is in Defaults and Benchmarks.