Getting Started
This page assumes the bundle is installed and the Generic Data Index runs on OpenSearch or Elasticsearch. Embeddings are off by default: they add fields to your search index and send content to an external inference service, so nothing happens until you opt in.
1. Pick a model
The bundle ships no model and has no built-in default endpoint. Two decisions matter:
- Modality. A text model covers semantic search and duplicate detection over data objects and the text of assets. Image search needs an image model, paired with a text model that embeds the incoming query into the same latent space, see Cross-modal models.
- Language coverage. If your users search in more than one language, pick a multilingual text model. Retrofitting this later means re-embedding everything. Localized fields are embedded in Pimcore's system default language; changing that language changes every object's identity key, so the affected vectors re-embed on the next indexing pass.
For a starting point rather than an evaluation, use the models the bundle's own benchmarks use, see Defaults and Benchmarks. To compare candidates on your content, use the Evaluation Tool.
2. Serve the model over HTTP
The bundle never loads or downloads a model. It only calls an inference service that you run or subscribe to. Out of the box it speaks the OpenAI-compatible embeddings shape, which most embedding servers and hosted APIs expose.
Inference Service covers hosting options, how to get the model weights and the exact contract an endpoint must fulfil. Two points decide whether your first run succeeds:
- Vectors must be L2-normalized (unit length). Unnormalized vectors do not error. They rank partly by vector length and quietly ruin result quality.
- The first backfill is your heaviest inference burst. Embedding a whole catalogue on CPU-only hardware can take hours, which is why the model timeout defaults to 120 seconds.
If no available service fits your model, implement your own provider, see Customization.
3. Configure embeddings in Pimcore Studio
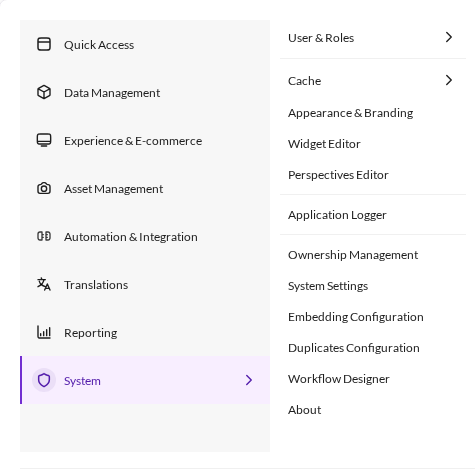
Open System > Embedding Configuration. The screen is admin-only.

Work through the four tabs. Every field is documented in the Configuration reference.
- General: switch Enabled on.
- Scope: switch Embed assets and Embed data objects on and pick the asset types and classes to embed. Both are empty by default, so nothing is embedded until you choose.
- Models: Add model for each model, with its endpoint, model name and dimension. Press Test on a model to check that the endpoint answers and returns the dimension you configured.
- Usages: map each capability (semantic text search, object deduplication, image search, image deduplication) to one of your models.
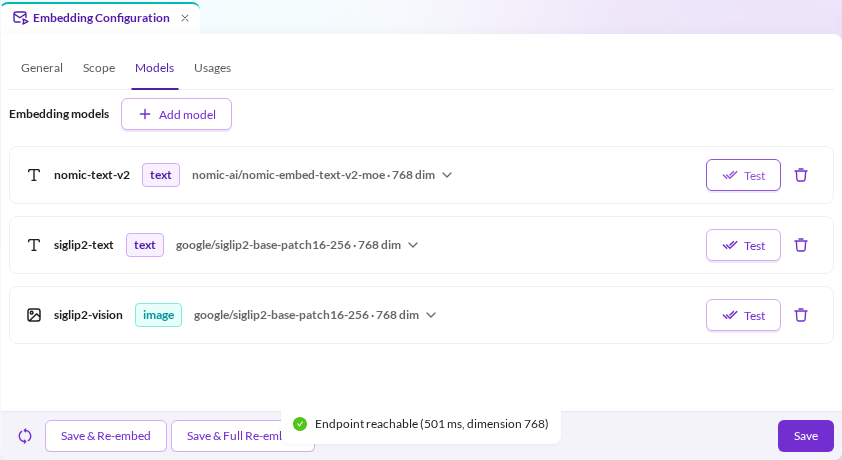

Then press Save.
4. Run the workers
Embedding generation is asynchronous. Two transports must be consumed — the index queue and the embedding queue:
bin/console messenger:consume pimcore_generic_data_index_queue
bin/console messenger:consume pimcore_backend_power_tools_embedding_queue
Run the embedding queue in its own worker, or several. Embedding batches are slow compared to structural indexing, and sharing a worker lets them starve normal index updates. In production both belong under a process supervisor.
5. Embed the existing content
New and edited elements are embedded automatically from now on. Existing content needs one pass: press Save & Re-embed in the editor. It saves the configuration, brings the index mappings in line with the current scope, and queues the whole scope for embedding. Existing vectors are reused from the cache wherever the content and model are unchanged.
This is also what prepares the indices on a first enable, so no index command is needed. On OpenSearch the
vector fields require the index.knn setting, which cannot be added to an index that was created without
it; where that applies, the affected index is rebuilt and its alias swapped as part of the run. Expect the
first run to take longer for that reason.
Save & Full Re-embed regenerates every vector with fresh inference calls and ignores the cache. Use it after changing the serving side of a model, not for a first run.

Both buttons return as soon as the work is queued. The banner above the tabs reports progress while the run drains, see Progress and Cancellation.
6. Verify
The editor answers this on its own. When the run finishes, the status line reports how many elements are
still missing a vector and how many failed, and Pimcore notifies the user who started the run. 0 missing
means every eligible element carries vectors — there is nothing else to run. For what the numbers represent while
a run is still going, see Progress and Cancellation.
"Eligible" is the element scope plus what can actually produce input: an allowlisted data object class
(Concrete objects and their variants, never folders), image assets whose thumbnail rasterizes to a usable
raster, and document or text assets of a configured type. A document whose text cannot be extracted — a
scanned PDF, say — is still embedded from its identifying context (name, path, metadata), so it is never
reported as missing.
Finally, confirm quality end-to-end with a semantic query in Studio's search, or run the Evaluation Tool against label files.
Checking from the command line
Where a script or a CI job needs the same answer, the reconciler scans the live index for elements whose vector field is absent:
bin/console bpt:embeddings:reindex --reconcile
This is not a read-only check: every element it finds is re-enqueued. Run it only once a run has finished. During a run, everything not yet embedded counts as missing, so the whole remainder is queued a second time — duplicate work, and the extra index-queue rows make the run look further from completion than it is.
It scans at most 10,000 elements per field and says so when it stops there; re-run it to continue.
Troubleshooting the first run
| Symptom | Likely cause |
|---|---|
| No vectors appear at all, no errors | Most often the scope: no classes selected on the Scope tab (no object is embedded) or no asset types selected (no asset is embedded). Then check Enabled and the Usages tab. |
| A newly added class indexes but never gets vectors | Its index mapping has not been updated yet. Press Save & Re-embed, which verifies and updates the mapping first. Elements indexed in the meantime were auto-marked for backfill and heal on that run. |
| A document has vectors but content queries never find it | Only its name, path and metadata were embedded: a scanned or image-only PDF has no text layer and there is no OCR, or pimcore.assets.document.process_text is disabled so no PDF text is extracted at all. |
| Search returns results but ranking looks random, scores nearly identical | The service returns unnormalized vectors, see serving invariant 1. |
| Vectors missing for some elements only | Generation failed for those; they are marked for backfill. Press Save & Re-embed again and check the worker logs. |
| A worker starts and exits immediately without output | A stale worker-restart signal. Clear it with bin/console cache:pool:clear cache.messenger.restart_workers_signal, then consume again. |
| How do I know a re-embed finished | Watch the progress banner, or wait for the Pimcore notification sent to the user who started the run, see Progress and Cancellation. |
| Everything re-embeds on every reindex | An identity-key input is changing, see When vectors are regenerated. |
index.knn / unknown setting errors on Elasticsearch | index.knn is OpenSearch-only; the bundle omits it on Elasticsearch. Recreate the index after switching engines. |
Turning it off again
Switch Enabled off on the General tab. That stops all embedding behaviour in one place — mapping, generation, indexing and kNN querying — whatever the configured models and usages say. Already-stored vectors stay in the index until it is recreated; the commands refuse to run, and the kNN search modifier becomes a no-op instead of calling the inference service.